YouTube iframe API: what 993 bytes actually ship
Paste one script tag on your page and you enable YouTube’s whole iframe embed API:
<script src="https://www.youtube.com/iframe_api"></script>The response body is 993 bytes uncompressed, 572 bytes over the wire with gzip. Every embeddable JS SDK (Vimeo, Safie, Mux, Video.js, whatever you build) solves the same set of problems in that first request. YouTube’s loader happens to solve them tersely enough to read end to end. Walking those 993 bytes alongside the browser-observable HTTP context turns up seven patterns that generalise to any script-tag SDK.
Measurements are from a fetch on 2026-08-08 (build ID 854a788e). The build ID rotates; the shape does not.
What actually comes down the wire
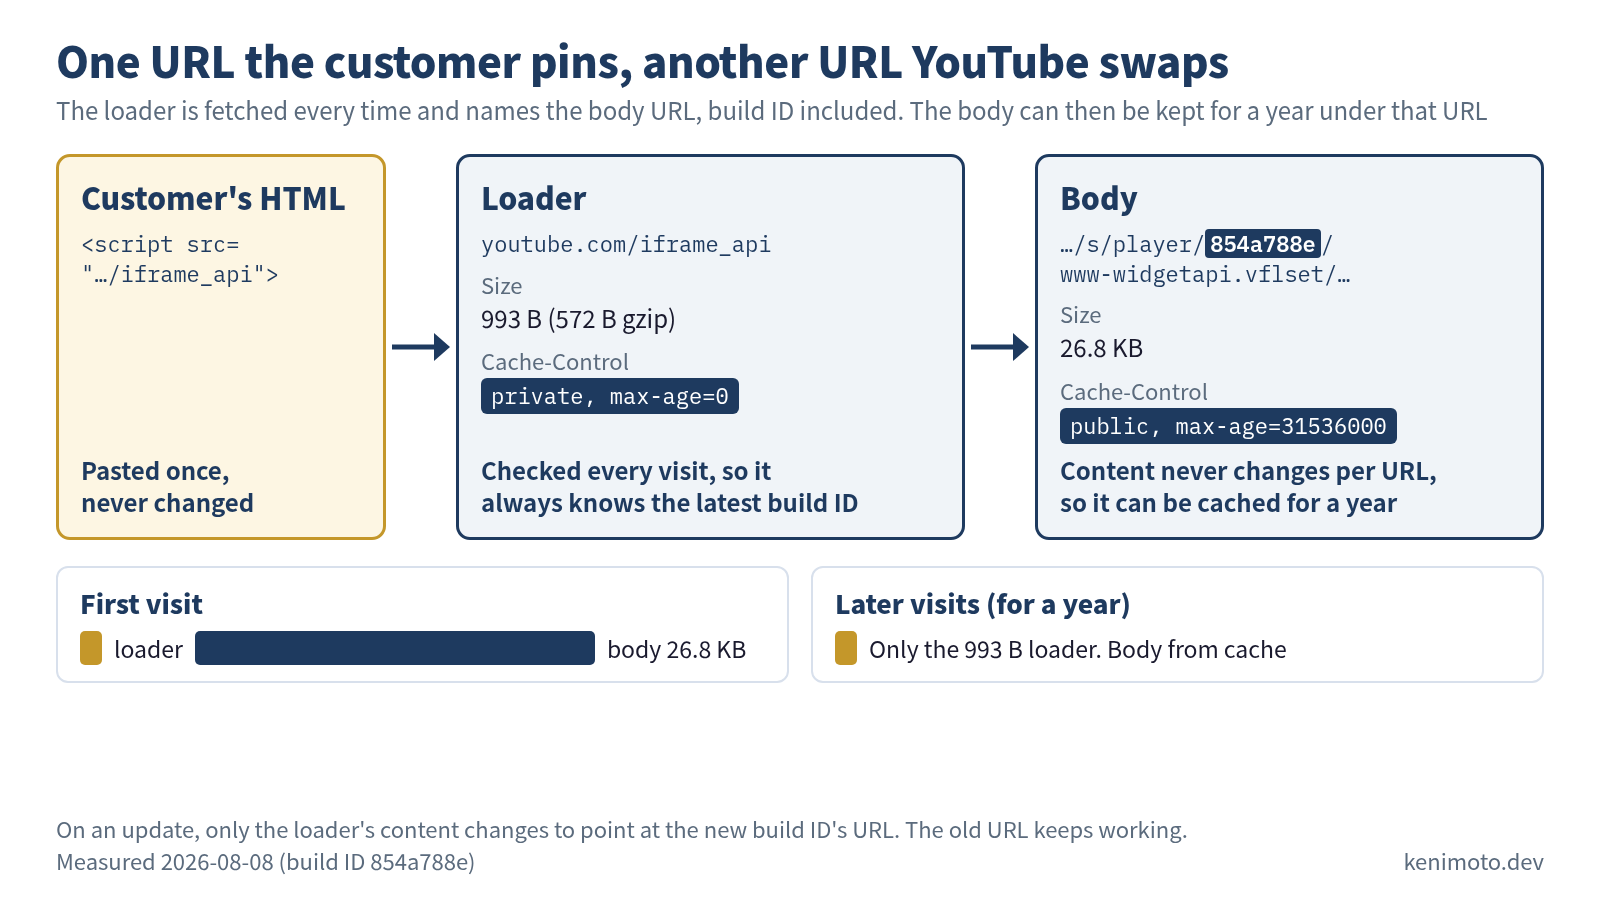
Two requests, not one, and the split is deliberate.
| Request | URL | Body size | Cache-Control | What it does |
|---|---|---|---|---|
| Loader | youtube.com/iframe_api | 993 B raw / 572 B gzip | private, max-age=0 | Injects the body script and sets up the global |
| Body | youtube.com/s/player/854a788e/www-widgetapi.vflset/www-widgetapi.js | 26.8 KB | public, max-age=31536000 (1 year) | The actual widget code |
The loader URL is stable: customers put it in their HTML once and never change it. The body URL contains the build ID (854a788e), so whenever YouTube ships an update the loader points at a new URL and the old one keeps working for anyone whose page cache hasn’t refreshed. It’s a redirect-through-content: the loader is the redirect, so an in-flight browser doesn’t need a 302 round trip.
The loader in full
Formatted (the shipped version is one long line):
var scriptUrl = 'https://www.youtube.com/s/player/854a788e/www-widgetapi.vflset/www-widgetapi.js';
try {
  var ttPolicy = window.trustedTypes.createPolicy('youtube-widget-api', {
    createScriptURL: function (x) { return x }
  });
  scriptUrl = ttPolicy.createScriptURL(scriptUrl);
} catch (e) {}

var YT;
if (!window['YT']) YT = { loading: 0, loaded: 0 };
var YTConfig;
if (!window['YTConfig']) YTConfig = { host: 'https://www.youtube.com' };

if (!YT.loading) {
  YT.loading = 1;
  (function () {
    var l = [];
    YT.ready = function (f) { if (YT.loaded) f(); else l.push(f) };
    window.onYTReady = function () {
      YT.loaded = 1;
      var i = 0;
      for (; i < l.length; i++) try { l[i]() } catch (e) {}
    };
    YT.setConfig = function (c) {
      var k;
      for (k in c) if (c.hasOwnProperty(k)) YTConfig[k] = c[k];
    };
    var a = document.createElement('script');
    a.type = 'text/javascript';
    a.id = 'www-widgetapi-script';
    a.src = scriptUrl;
    a.async = true;
    var c = document.currentScript;
    if (c) {
      var n = c.nonce || c.getAttribute('nonce');
      if (n) a.setAttribute('nonce', n);
    }
    var b = document.getElementsByTagName('script')[0];
    b.parentNode.insertBefore(a, b);
  })();
}
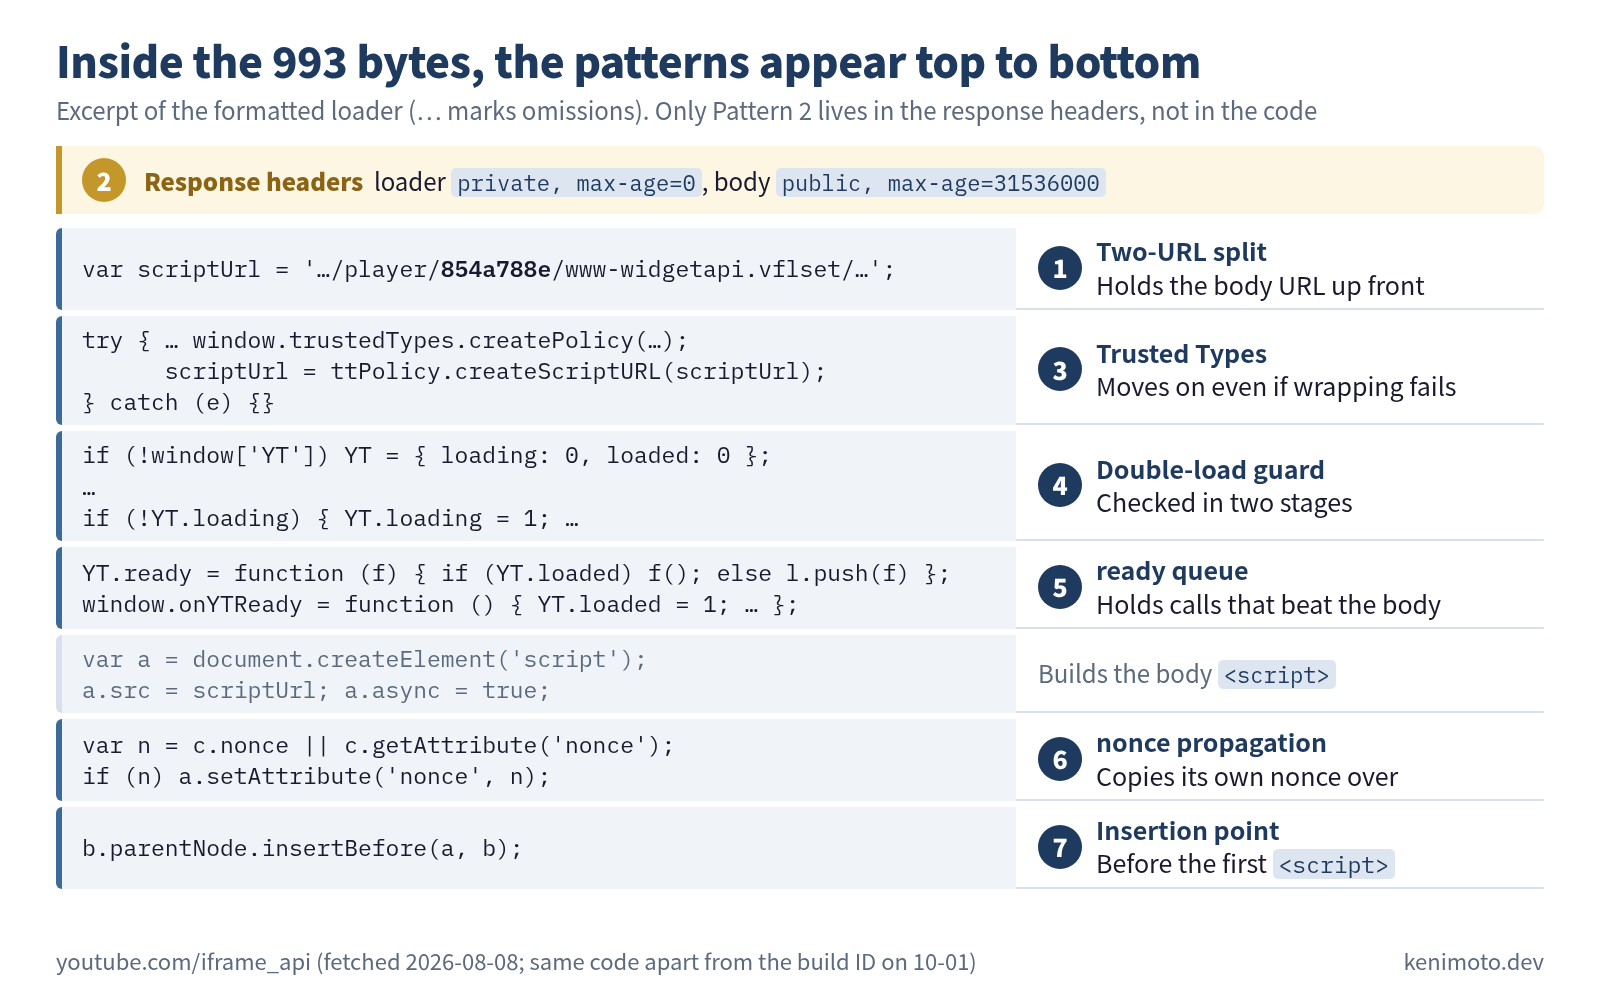
That’s it. Seven patterns, in order.
Pattern 1: the two-URL split
scriptUrl is the very first thing declared. The loader exists to point at it. There’s no attempt to inline widget code into the loader itself. The loader stays tiny (993 B) so it fits in a single TCP round trip and can be cached cheaply.
You could imagine an alternative where a single URL streams the full widget. YouTube doesn’t do it, and neither does Safie, which fronts its SDK with an iframe (Vimeo’s player.js is a single file). The reason is boring: one URL customers pin, one URL you rotate. The loader is the stable contract with the customer’s HTML; the body is the versioned artifact you replace on your schedule.
Pattern 2: the cache-control asymmetry
The loader’s Cache-Control: private, max-age=0 looks wasteful, since every visit revalidates. It isn’t. Max-age=0 with no ETag means the browser always fetches the loader, so it always learns the current build ID. The body URL contains that build ID, so once fetched it can sit in the browser cache for a year (serving hash URLs with max-age=31536000 is common practice; YouTube’s body is served with public, max-age=31536000, without immutable).
The math works out well for repeat visitors: 993 bytes of loader on every visit (or ~572 B compressed), 26.8 KB of body once and then never again for a year. First-time visitors pay both; returning visitors pay one request. Compare with a monolithic 27 KB script served with a shorter TTL: every visitor pays the whole thing on every cache miss.
The catch: if your loader isn’t tiny, the always-revalidate cost eats you. YouTube’s 993 B is fine. If your loader were 30 KB gzipped, I would want a different strategy.
Pattern 3: Trusted Types with a try/catch fallback
try {
  var ttPolicy = window.trustedTypes.createPolicy('youtube-widget-api', {
    createScriptURL: function (x) { return x }
  });
  scriptUrl = ttPolicy.createScriptURL(scriptUrl);
} catch (e) {}
Trusted Types (require-trusted-types-for 'script') is a CSP directive that forbids assigning plain strings to sinks like script.src. Under that policy, a.src = 'https://...' throws. You have to first pass the string through a named policy that returns a TrustedScriptURL.
YouTube.com’s own response headers include content-security-policy: require-trusted-types-for 'script'. So when the loader runs in that context (which it will if a YouTube-owned page is what loaded it, or if a customer’s page opts into Trusted Types), the raw string has to be laundered through a policy first. The identity function (return x) does no sanitization. The security model here is “did this URL come out of a named policy, yes or no”, not “is this URL safe”. YouTube trusts its own strings; the ceremony is what CSP requires.
The try/catch matters. Some browsers don’t have window.trustedTypes (Firefox has supported it since 148, Safari since 26), and createPolicy throws under a variety of conditions (name collision, disallowed name). The fallback is: if any of this fails, keep the raw string and hope the host page isn’t enforcing Trusted Types. On a customer page that isn’t under that policy, the raw string works fine.
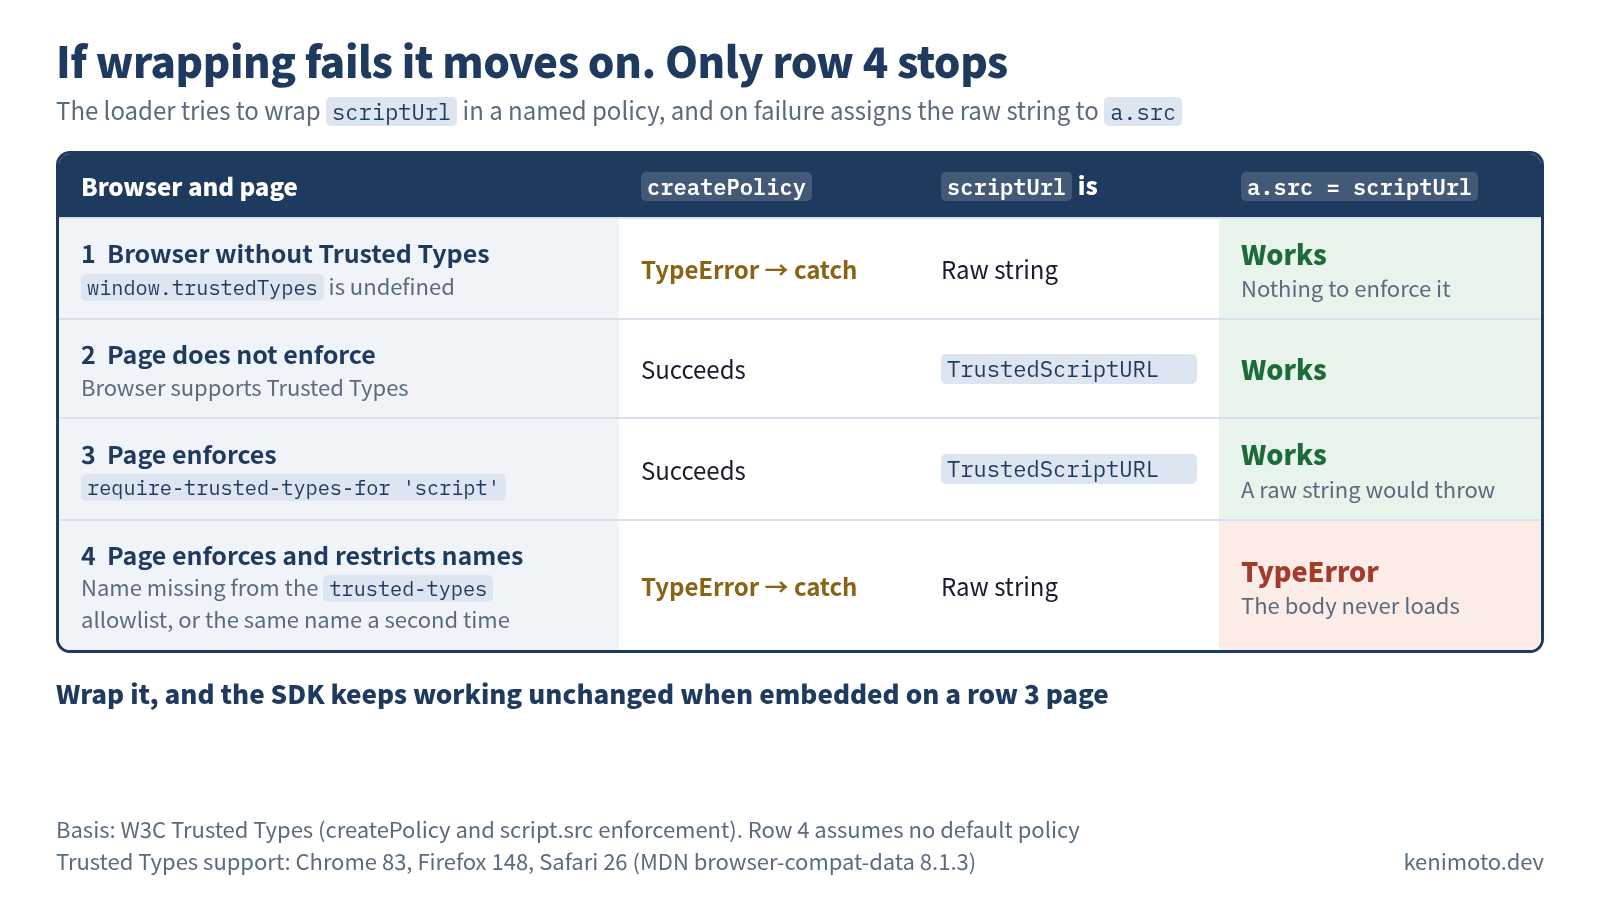
Steal the pattern: even if you don’t ship on a Trusted Types page today, wrapping the URL is cheap. When a customer inherits a strict CSP, your SDK keeps working without changes.
Pattern 4: global namespace guards
var YT;
if (!window['YT']) YT = { loading: 0, loaded: 0 };
Double-loading happens. Tag managers duplicate script tags, careless integrations paste the same snippet twice, someone else on the page has already loaded the widget. The guard says: if YT already exists, don’t touch it. The if (!YT.loading) further down is the same defense one layer deeper: if a previous copy of the loader already started, don’t inject a second body script.
Four of the five SDKs I looked at have some version of this. YouTube’s guard is stock idiom. Vimeo uses data-vimeo-initialized on the element. Mux uses customElements.get() to detect that its Web Components already exist. Video.js sets a player property on each element it has set up and skips elements that already have one. I found no window.Safie existence check in Safie’s loader (re-fetched 2026-09-30). You need this from day one; the day you don’t have it is the day a customer’s tag manager fires your snippet twice and their console fills with duplicate-registration errors.
Pattern 5: YT.ready() queues callers who arrive early
var l = [];
YT.ready = function (f) { if (YT.loaded) f(); else l.push(f) };
window.onYTReady = function () {
  YT.loaded = 1;
  var i = 0;
  for (; i < l.length; i++) try { l[i]() } catch (e) {}
};
The body script hasn’t downloaded yet when the loader finishes. But customers write:
<script src="https://www.youtube.com/iframe_api"></script>
<script>
  YT.ready(function () { /* use YT.Player */ });
</script>
…expecting YT.ready to just work. It does, because the loader defines YT.ready immediately, and it either fires the callback (if the body has finished loading) or pushes it into l. The body script, when it lands, calls window.onYTReady(), which sets loaded = 1 and flushes the queue.
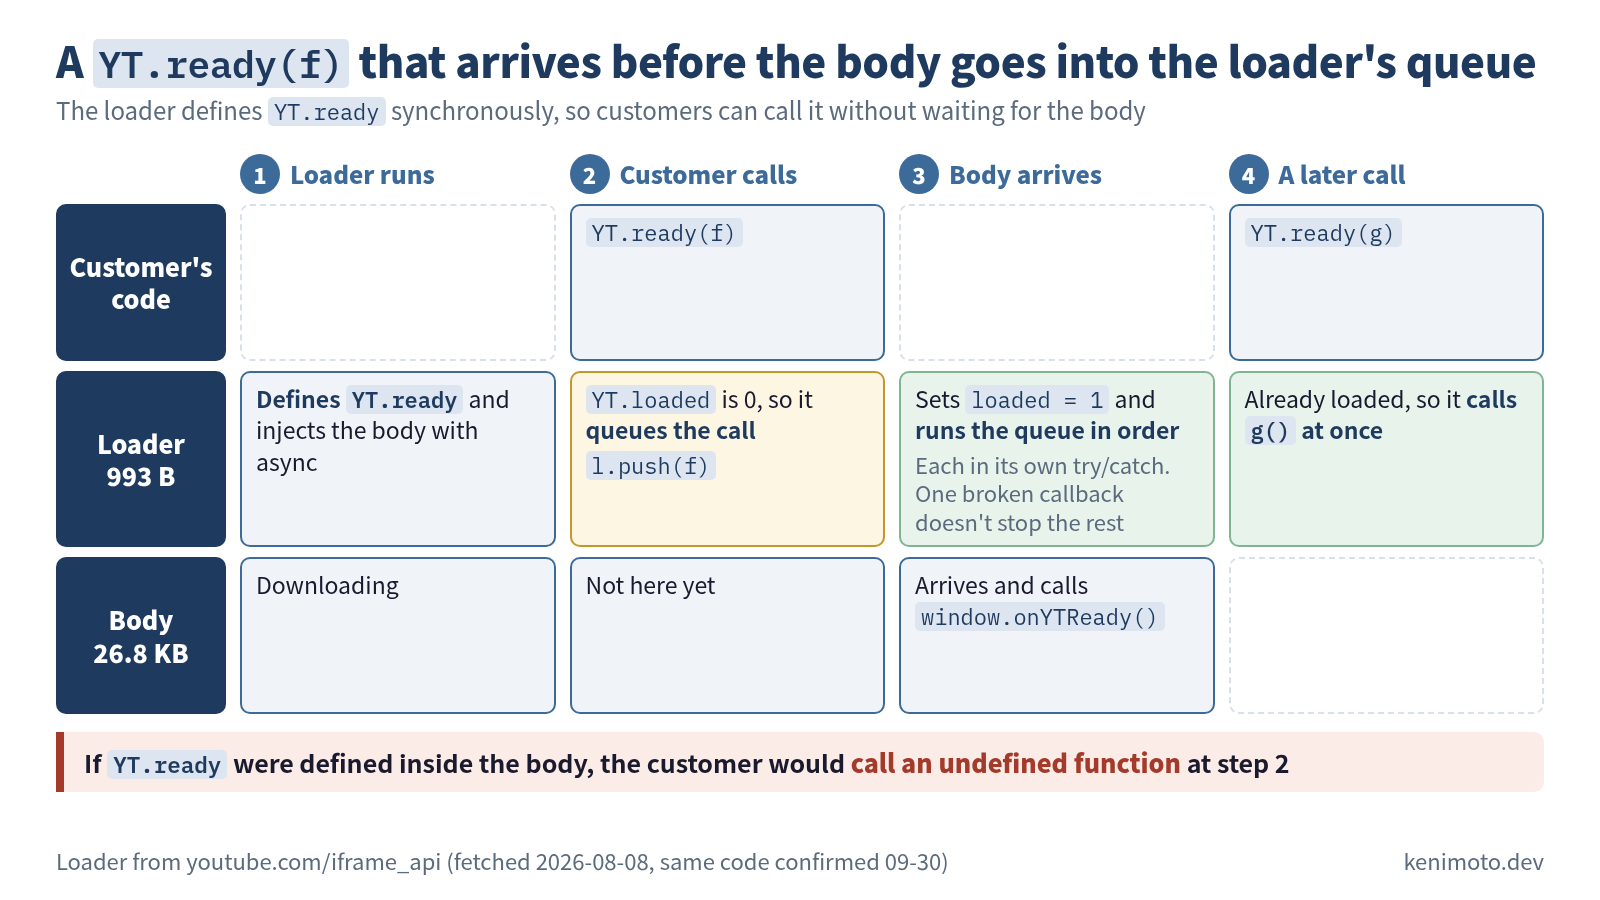
Two things worth stealing: the try/catch inside the callback loop (one broken callback doesn’t stop the rest), and the fact that YT.ready() is defined synchronously in the loader. If it were defined by the body script, any customer that called it before the body arrived would hit an undefined function.
Pattern 6: currentScript.nonce propagation
var c = document.currentScript;
if (c) {
  var n = c.nonce || c.getAttribute('nonce');
  if (n) a.setAttribute('nonce', n);
}
Under a CSP that allows scripts by nonce, such as script-src 'nonce-XYZ' (YouTube’s own pages set one, and so do many security-conscious customer pages), only scripts marked with the current request’s nonce are allowed to execute. Under a nonce-only policy, scripts injected without a nonce get blocked. Under a policy that adds 'strict-dynamic' (YouTube’s own pages use this kind), a script that a trusted script injects with createElement inherits that trust, so it runs even without a nonce. Copy the nonce and the loader works under either policy.
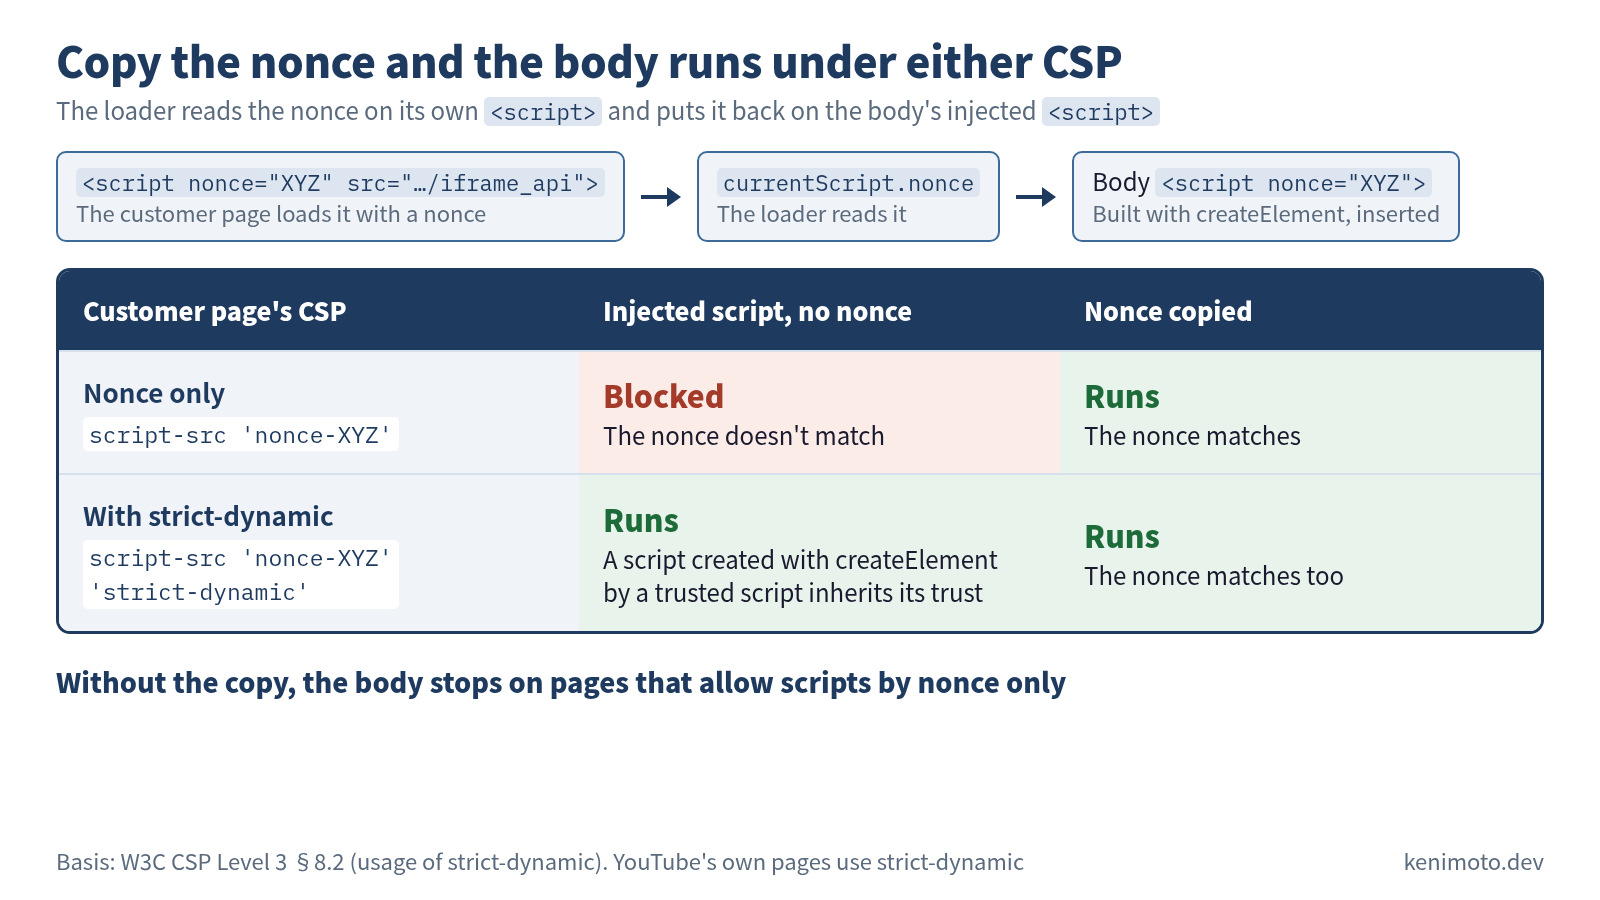
The loader reads its own nonce off document.currentScript and copies it to the body script it injects. Two subtleties:
c.nonceis the DOM property;c.getAttribute('nonce')is the fallback. The property comes first because browsers hide the attribute’s value fromgetAttributefor security reasons (Chrome 147 returned an empty string while the property still held the value).getAttributeis there for older browsers that lack thenonceproperty (Firefox added it in 75).document.currentScriptreturns the element of the classic script that is running synchronously right now. If a bundler concatenates the loader with other code into one classic script, you get that bundle’s<script>element, and since the nonce is shared across the page, the copy still works. It isnullinside a module script (type="module", or anything loaded viaimport) and inside callbacks that run later, such assetTimeoutor event handlers. Run the loader through a bundler that outputs ESM, or wrap it in something that defers execution, andccomes backnull, so the body is injected without a nonce.
If your SDK is likely to be embedded on strict-CSP pages, this is the pattern. Copy the nonce; do it defensively; document to customers that they need to load the loader as a classic script tag (not type="module", not inside a deferred wrapper).
Pattern 7: the classic insertion point
var b = document.getElementsByTagName('script')[0];
b.parentNode.insertBefore(a, b);
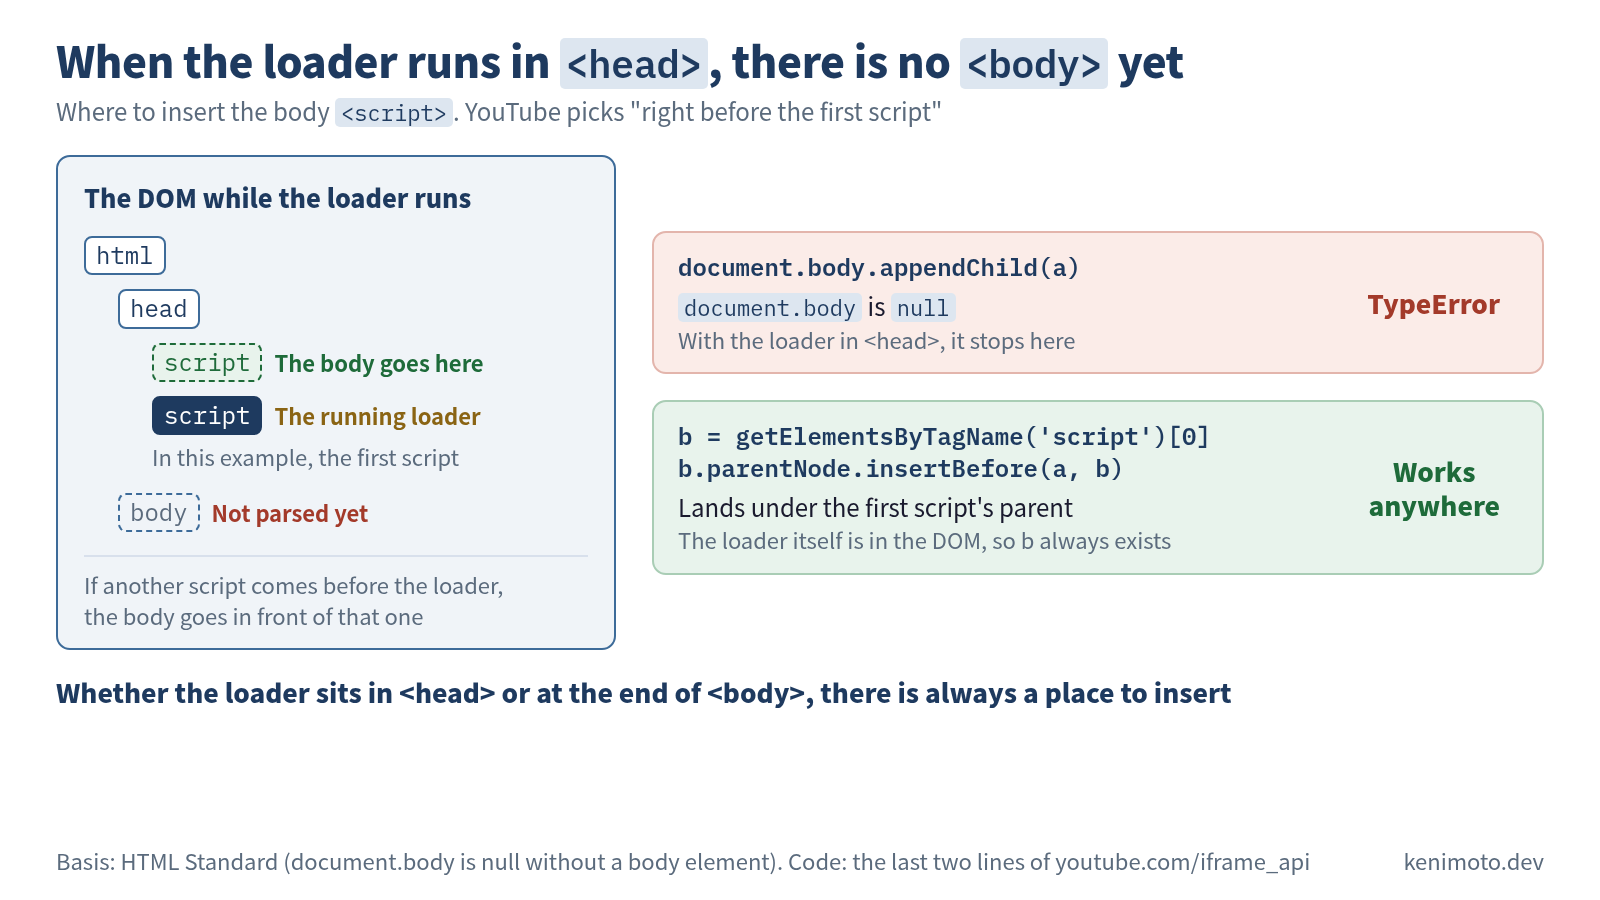
The old Google Analytics snippet made this idiom common, and YouTube’s loader uses it too. It works everywhere, because every page that runs any script has at least one <script> in the DOM by the time your loader executes (yours). Inserting before it puts you in the right document, in <head> when possible, without needing to know whether <body> exists yet or whether document.body is null.
Of the modern alternatives, document.body.appendChild has the edge case. When the loader runs in <head>, <body> hasn’t been parsed yet, so document.body is null. document.head.appendChild almost always works on an HTML page: even if the author left out <head>, the parser creates the head element before the first script runs. (It is null mainly in XHTML written without a <head>.) Making b the first <script> in the document (there is always at least one: the loader itself) and inserting with insertBefore(a, b) spares you from thinking about any of these cases.
What to steal for your own SDK
Seven operational upsides in one 993-byte file:
- Version your body URL with a hash; keep the loader URL stable. One URL customers pin, one URL you rotate.
- Cache the loader for zero seconds, the body for a year. Repeat visits pay the loader’s small revalidation only.
- Wrap script URLs in a Trusted Types policy with a
try/catchfallback. Cheap now, essential when a customer’s CSP tightens. - Guard against double-load from the very first commit. Tag managers will fire your snippet twice.
- Define your
.ready()queue in the loader, not the body. Callers who arrive before the body script must not hit an undefined function. - Copy
document.currentScript.nonceonto the injected<script>. Strict CSPs are increasingly common; this is the compatibility fix. - Insert the injected
<script>before the first<script>on the page. You never needdocument.headordocument.bodyto exist yet.
The two-stage split is the foundation the other six patterns stand on. If your SDK is one monolithic file, you can’t do half of these. If it’s split, the loader gets small enough that annotating every byte becomes viable. That is what let YouTube ship a loader you can read end to end in ten minutes.
The same split shows up at a much smaller scale. When I added a support overlay across my own product pages, the injected tag was one line; the UI, the analytics and the per-URL rules all lived in a single file on the main site, so a redesign never touches the products. That build is written up in Ship a product, get a support button for free.
This is part 1 of a series teardown of five real script-tag JS SDKs (YouTube, Safie, Vimeo, Mux Player, Video.js). See the series pillar for the full table of contents. Measured 2026-08-08 against build 854a788e.
Was this article helpful?